I started keeping a log on July 1st. Simple premise: every spreadsheet I handed to Claude or ChatGPT for analysis, I noted what it got wrong.
By day 30, I had seven entries. By day 60, twenty-two. By day 90, I had enough patterns to know something structural was happening — not random model hallucinations, but consistent failure modes triggered by specific data conditions I could actually prevent.
The moment it crystallized was a Thursday afternoon in late August. I’d asked Claude to summarize average lead times by supplier from a 14-month dataset. The number it returned was off by 11 days from my own manual calculation.
Not close. Not rounding error territory. Eleven full days.
I spent 40 minutes tracing it. The problem wasn’t the model. It was my data. Column B had two different date formats — YYYY-MM-DD from our ERP system and MM/DD/YY from a vendor portal I’d copy-pasted in February. Claude treated them both as text strings, picked the rows it could parse, averaged those, and silently discarded the ones it couldn’t. No warning. No flag. Just a confident-looking number that was wrong.
I should have caught this in step one of my own data prep process. I didn’t.
That’s when I started auditing systematically. Here’s what I found.
Three errors. All silent.
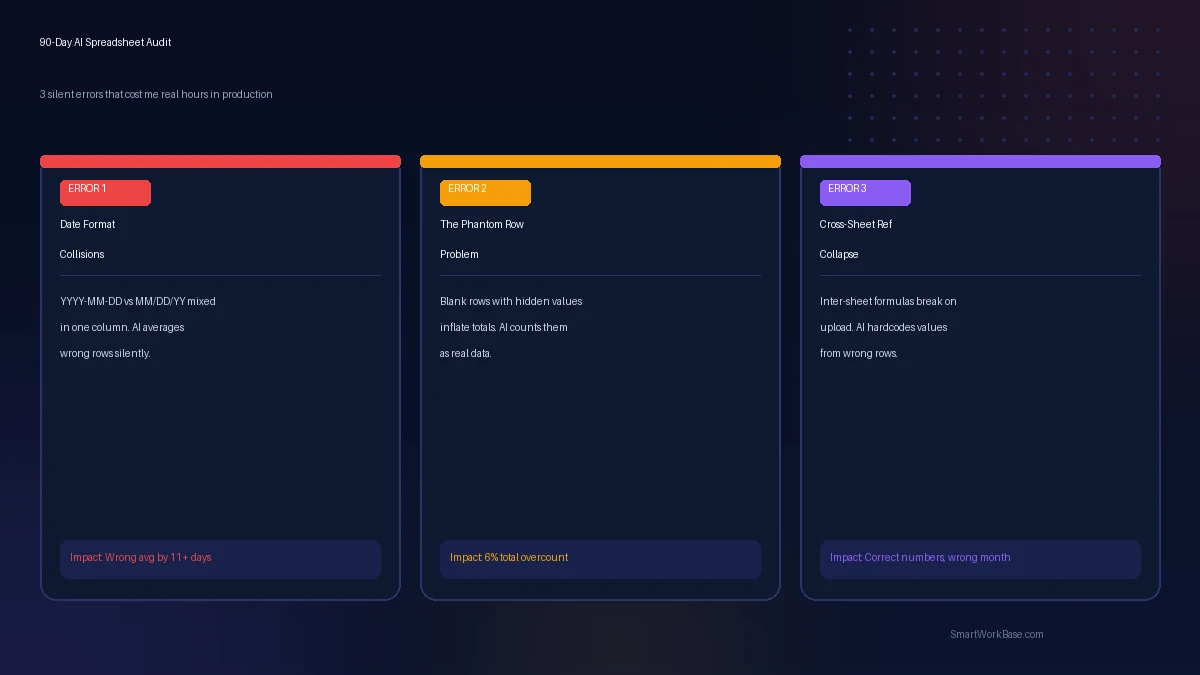
Error 1: Silent Date Format Collisions
This was the most common issue. In 14 out of 22 cases where the model returned a suspicious aggregate, mixed date formats were the culprit.
The setup is predictable: you build a master file over months. The first half of the data comes from one source with one date format. A new portal, a different team’s export, a manual entry — and suddenly you’ve got two formats coexisting in the same column. Excel shows them all fine. They look identical in a grid view. The model doesn’t distinguish.
When I handed a file with both 2026-01-15 and 01/15/26 in Column B to ChatGPT and asked for a monthly breakdown, it quietly grouped by the string prefix. 2026-01 became one bucket. The 01/15 rows landed in a separate, unnamed bucket. The monthly total was short by 30 rows.
I only caught it because I already knew the right answer. Most of the time, I don’t.
Error 2: The Phantom Row Problem
Excel sheets accumulate junk. Rows with a formula but no values. Rows with a single space in one cell. Rows that look blank but carry a hidden line break. To you and me, they’re empty. To an AI processing a CSV export, they’re rows with data.
I had a weekly dispatch tracking sheet with 312 rows of real data and — I counted afterward — 19 phantom rows scattered throughout. When I asked Claude to count the total number of shipments processed, it returned 331. The real answer was 312. A 6% overcount that, in a supplier performance report, would have been embarrassing.
The model had no way to know those rows were phantom. It saw cells with values — a space, a formula returning an empty string, a line break — and counted them. Perfectly logical behavior. Completely wrong output.
I still sometimes skip the phantom row purge when I’m in a hurry. The error rate reflects that.
Error 3: Cross-Sheet Formula References That Break on Upload
This one is nastier because it often produces a result that looks correct.
When you upload a multi-sheet Excel file to an AI for analysis, the model can’t follow inter-sheet references. A formula like =Sheet2!B14 in Sheet1 becomes meaningless the moment the file context collapses into a single parsed text stream. Worse: some AI tools attempt to rewrite those relative references as absolute values at parse time — and if Sheet2 didn’t upload correctly or loaded in the wrong order, the “absolute” values they hardcode are from the wrong rows entirely.
I caught this when Claude summarized my freight cost allocation sheet and returned unit costs that were exactly correct for a different month. Not random numbers. Correct numbers from the wrong sheet. It had resolved a cross-reference incorrectly and the result looked plausible enough to survive a quick glance.
Fifteen seconds to flatten. An hour if you don’t. I’ve paid that price.
The Pre-Flight Checklist I Now Run Before Any AI Touches My Data
Run this before handing any spreadsheet to an AI tool. Takes 4–6 minutes. Saves hours of cleanup.
## AI Spreadsheet Pre-Flight Checklist

### 1. DATE FORMAT AUDIT
[ ] Open column filter on every date column
[ ] Check for mixed formats (YYYY-MM-DD vs MM/DD/YY vs DD-Mon-YY)
[ ] If mixed: run Text-to-Columns → Date → fix to ISO format (YYYY-MM-DD) across all rows
[ ] Verify: =ISNUMBER(DATEVALUE(TEXT(A2,"YYYY-MM-DD"))) should return TRUE for all rows

### 2. PHANTOM ROW PURGE
[ ] Run: Ctrl+End → note the last row number the spreadsheet thinks it has
[ ] Compare to actual data row count (use COUNTA on key column)
[ ] If mismatch: select below last real row → Edit → Delete Rows
[ ] Run TRIM() on text columns; replace formulas returning "" with actual blanks

### 3. FLATTEN CROSS-SHEET REFERENCES
[ ] Copy any formula cells that reference other sheets → Paste Special → Values only
[ ] If multi-sheet file: consolidate to one sheet before upload
[ ] Delete or hide all empty/unused sheets before exporting

### 4. DEFINE THE DENOMINATOR EXPLICITLY
[ ] Add a cell: Total_Rows = COUNTA(A:A) - 1 (exclude header)
[ ] Tell the AI: "This file has [N] data rows. Flag if your count differs."

### 5. NUMERIC VS TEXT AUDIT
[ ] Check every column that should be numeric: =ISNUMBER(B2) spot-check
[ ] Look for leading apostrophes or trailing spaces (common in ERP exports)
[ ] Convert text-numbers: select column → Data → Text to Columns → Finish

### 6. ENCODING CHECK (FOR CSV UPLOADS)
[ ] Save As → CSV UTF-8 (not ANSI/Latin-1)
[ ] Open in Notepad to verify no garbled characters in vendor names

### 7. TELL THE AI WHAT YOU KNOW
[ ] Start your prompt with the expected output range
[ ] Example: "Expected: 47 suppliers, avg lead time ~22 days. Flag any result outside 15–30."
To be fair
I don’t want this to read as a blanket condemnation. It isn’t.
In the same 90 days, AI tools saved me a significant amount of real time on spreadsheet work — when the data was clean.
Formula generation. When I describe what I want in plain English, Claude consistently produces correct, efficient formulas. Array formulas that would have taken me 20 minutes of trial-and-error came back in under a minute. This is genuinely one of the best use cases.
Pattern detection in clean data. When I give the model a well-structured, single-sheet file with consistent formatting, it finds anomalies I’d have missed. On one logistics dataset, it flagged three suppliers with identical lead times across every order — a statistical impossibility that turned out to be a data entry error someone had been copy-pasting for four months. I wouldn’t have caught that manually. Not without a lot more time.
Restructuring and summarization. Turning a 500-row flat export into a readable executive summary? Solid. Converting a pivot-style table into a relational structure for database import? Reliable. These tasks play to the model’s strengths precisely because they don’t require numerical precision — they require structural transformation.
The divide is consistent: AI is reliable when it’s reorganizing or generating. It’s unreliable when it’s calculating on ambiguous or dirty data.
What changed after the audit
Rule 1: Never upload raw ERP exports without a pre-flight pass. ERP systems dump data with whatever format was configured when the report template was set up — sometimes years ago. The format may be internally consistent, but it’s rarely what the AI tool expects. One pass of format normalization eliminates the largest error class.
Rule 2: Always state the expected output first. Before I describe the task, I tell the model what I expect to see: “This file covers 6 months, 312 rows, 47 unique suppliers. Average lead time by my manual count is around 22 days.” If the AI returns something wildly different, I treat the output as suspect and trace back. This catches formula errors, phantom rows, and format collisions in under two minutes.
Rule 3: Flatten before you upload. Multi-sheet workbooks with inter-references are the single most reliable way to get plausible-but-wrong AI outputs. I now have an Excel macro that pastes-values-only and moves everything to Sheet 1 before export. Running it takes 15 seconds. Skipping it costs me an hour. I’ve skipped it anyway. Twice.
The numbers, honestly
| Method | Error Rate (my 90-day sample) | Time per File | Stress Level |
|---|---|---|---|
| Manual check (me only) | ~8% | 45–60 min | 🟡 Medium |
| Pre-flight checklist + AI assist | ~2% | 12–18 min | 🟢 Low |
| No check, raw AI upload | ~31% | 5 min (+ 60+ min cleanup) | 🔴 High |
The 31% raw error rate sounds alarming. It is. But it’s not the model failing — it’s dirty data being treated as clean data. The model did exactly what it was told to do.
I just hadn’t told it the right things.
A few questions
Does this apply to Google Sheets as well, or just Excel?
Both, with some differences. Google Sheets exports to CSV more cleanly in most cases, and the UTF-8 encoding issue is less common. But phantom rows, mixed date formats, and cross-sheet reference collapse all apply equally. The pre-flight checklist above works for either platform. If you’re exporting from Google Sheets, use File → Download → CSV and verify the output in a plain text editor before upload.
Which AI tool was more reliable overall — Claude or ChatGPT?
Honestly, the error rates were similar when I fed them identical files. Claude was slightly better at flagging when it was uncertain about date parsing — it would sometimes note “I detected two date formats; I’ve assumed YYYY-MM-DD for all calculations” which at least gave me a warning. ChatGPT with the Advanced Data Analysis tool (Code Interpreter) was better at catching phantom rows because it was actually running Python on the file. Neither was reliably correct on raw, uncleaned data. The pre-flight pass mattered more than the model choice.
Is there a way to automate the pre-flight checklist instead of doing it manually?
Yes, and I’ve started doing exactly that. I have a short Python script using pandas and openpyxl that runs checks 1 through 5 automatically and outputs a one-page report flagging any issues it finds. It takes about 8 seconds to run. I haven’t published it yet because I’m still refining it for different ERP export formats, but the core logic — checking dtype consistency, COUNTA vs shape mismatch, and cross-sheet reference detection — is solid. I’ll write it up properly in a future post.